Developed reinforcement-learning controllers for an autonomous kart simulator, investigating how agents learn stable navigation policies across racing tracks.
Approach
Modeled track navigation as a sequential decision problem and evaluated learned control strategies in simulation.
Overfitting experiment
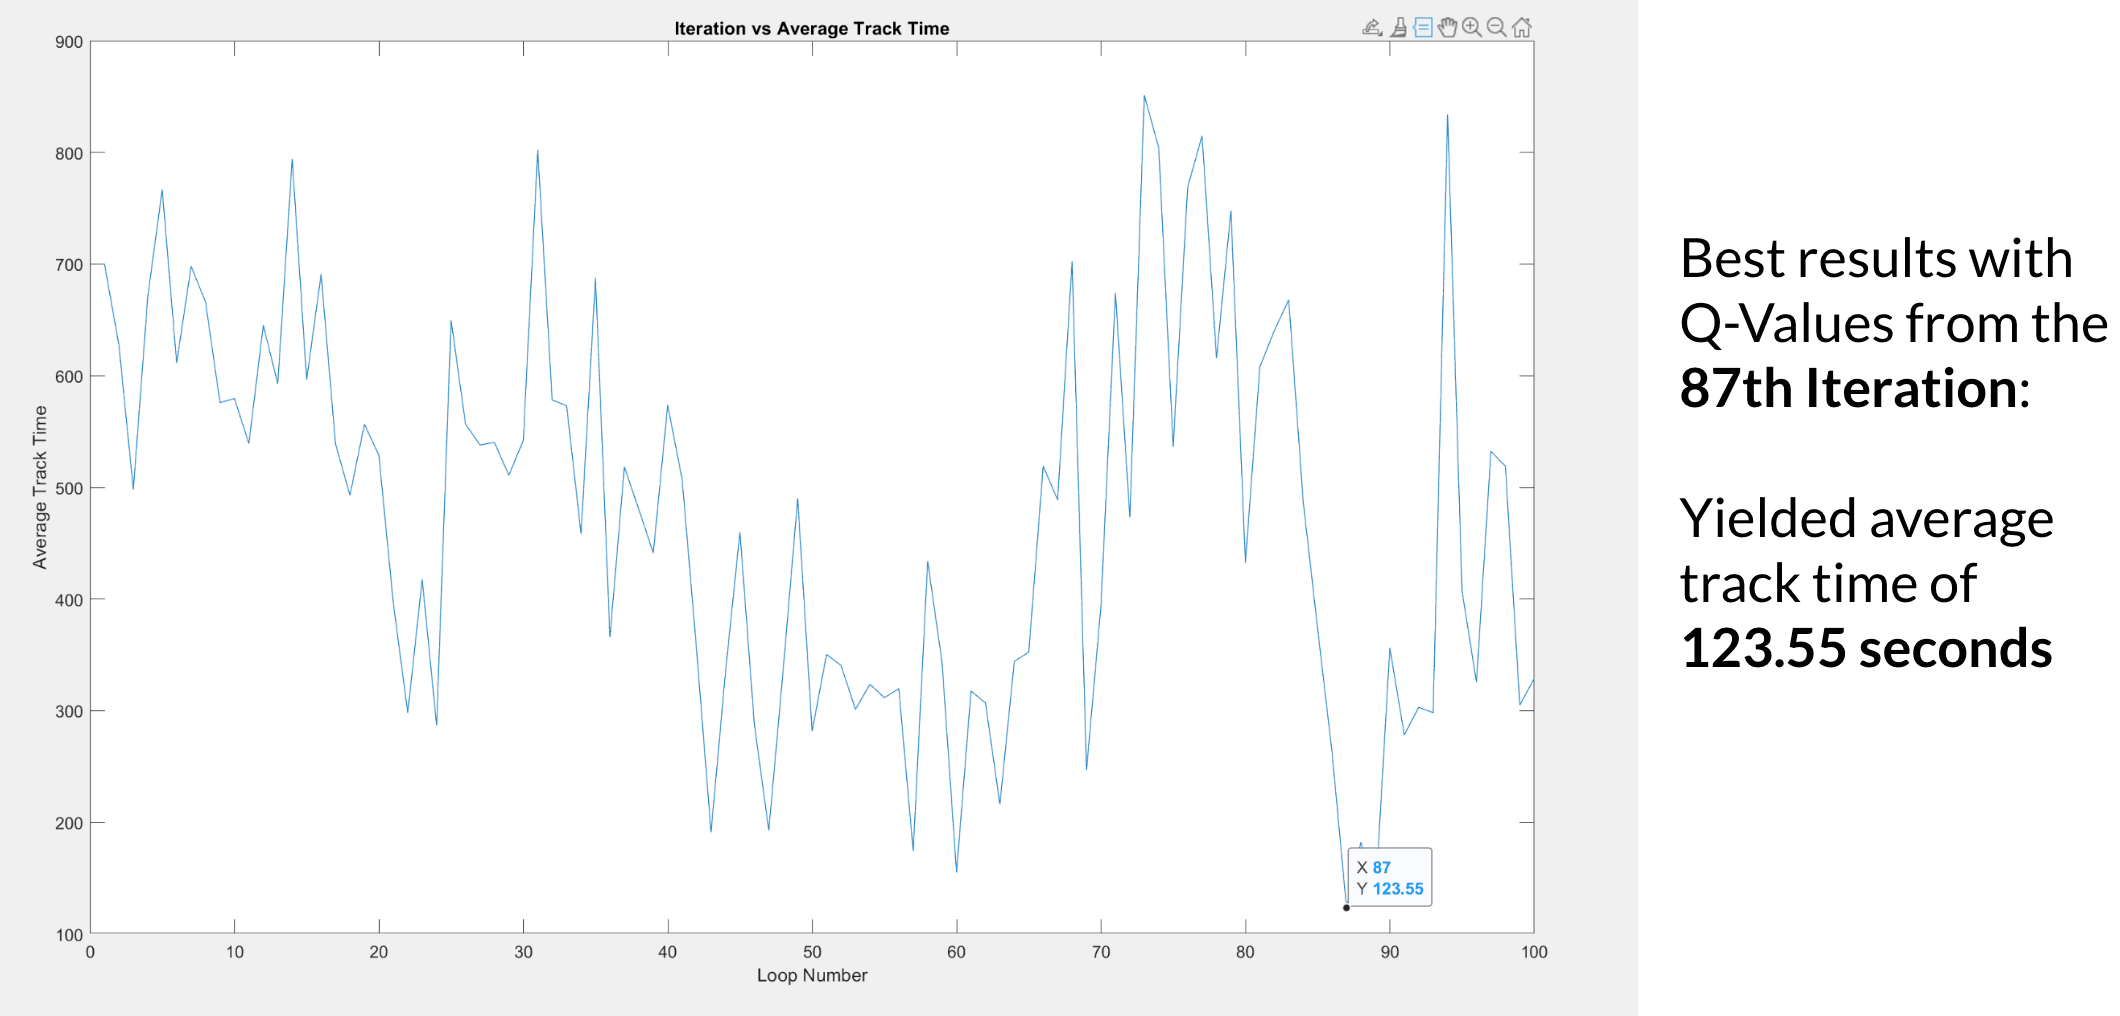
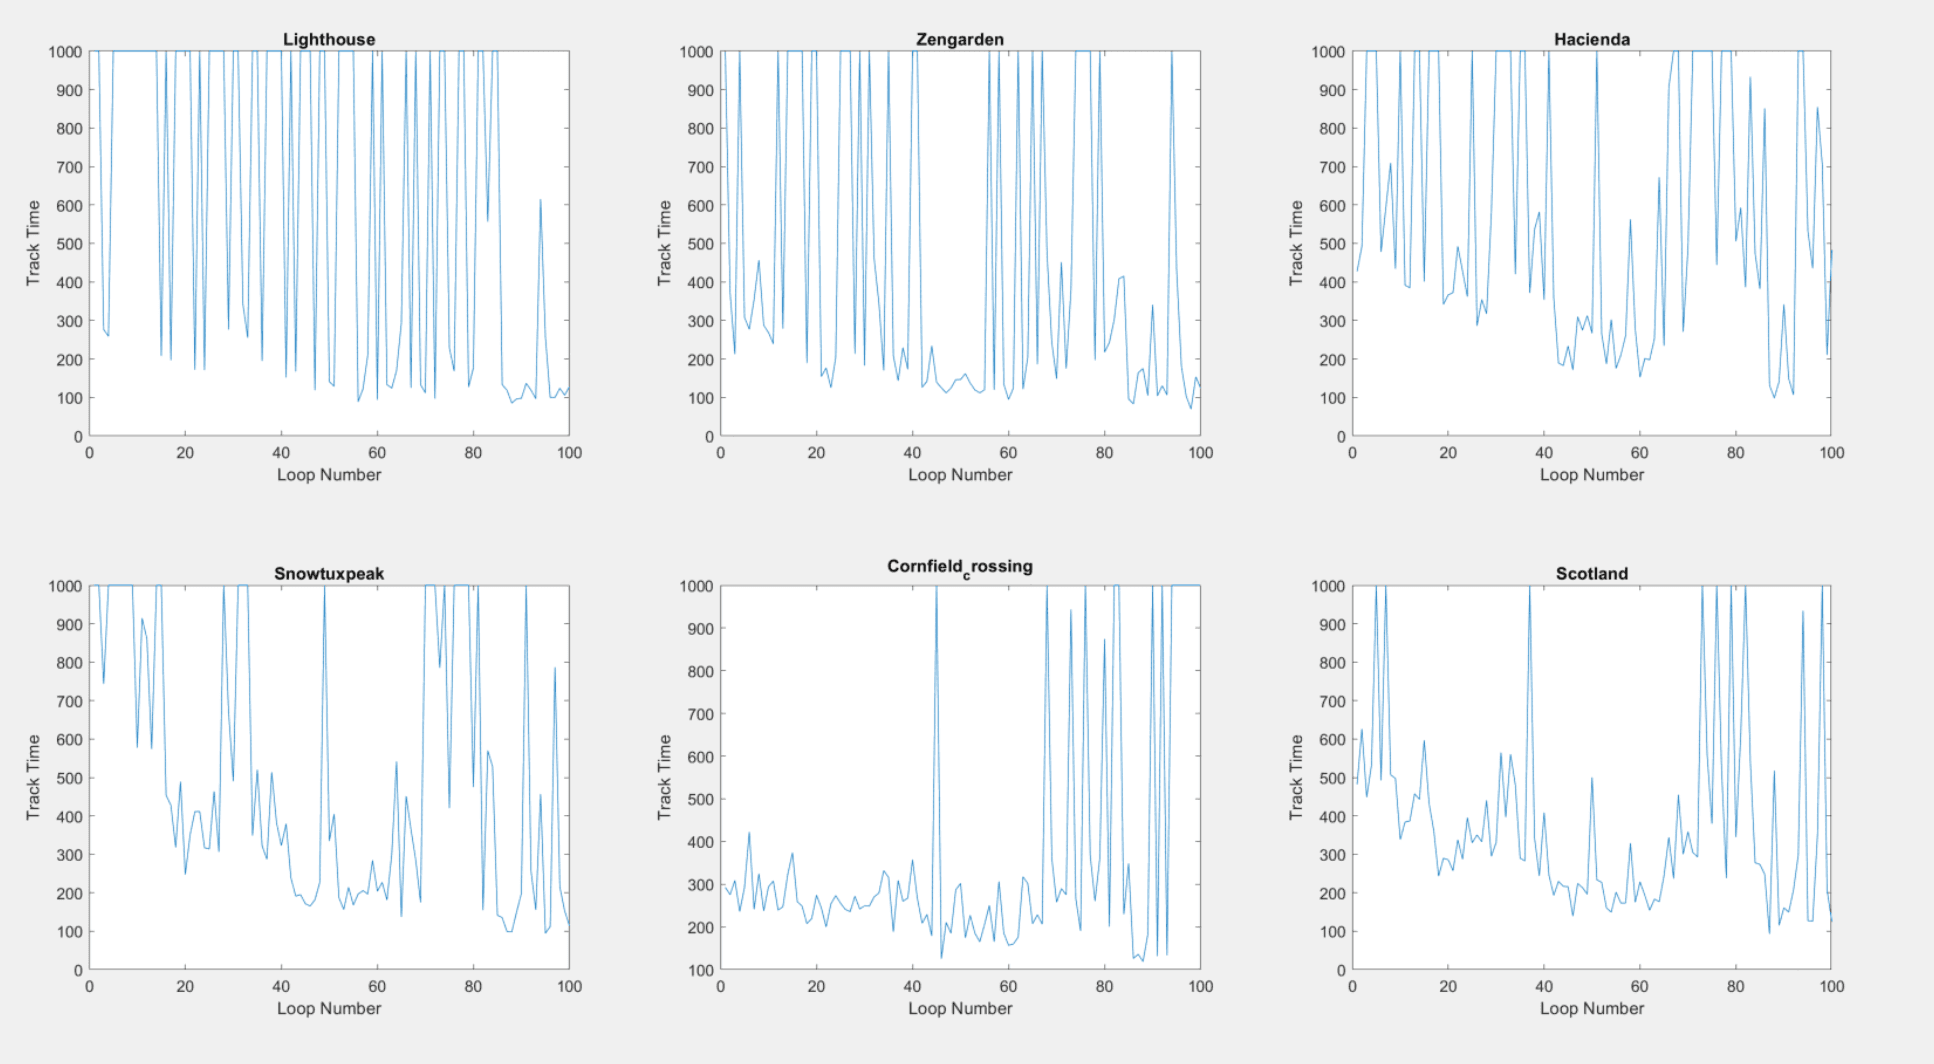
The accompanying simulation illustrates overfitting in reinforcement learning: a controller can become highly effective on a familiar track or training setup without learning a policy that generalizes reliably to different conditions. The experiment highlights why performance must be evaluated beyond the environment used for training.
My role
Implemented Q-learning and Double Q-learning agents, comparing training behavior and using separate value estimates to reduce overestimation bias without requiring a separate algorithm diagram.